
How do you give Claude Code access to GPUs through MCP?
Add the Nodus MCP server to Claude Code, Codex or Cursor with one command, then let the agent estimate, launch and watch GPU jobs under caps you set.
You give Claude Code GPUs by connecting it to a GPU platform’s MCP server, and on Nodus that is one command: claude mcp add --scope user --transport http nodus https://api-next.nodus-compute.ai/mcp, then /mcp to sign in. Nodus then lets the agent estimate, launch and watch GPU jobs on your account, and nothing gets created until you accept a dry-run cost estimate. The same server works in Codex, Cursor and any other client that speaks MCP.
Claude Code does not need a GPU on your laptop for any of this. It writes the training script locally and sends the work to the platform. The parts that need care are which server you connect, what you let the agent create, and the limits you put on each job.
What is the exact setup command for Claude Code, Codex and Cursor?
Section titled “What is the exact setup command for Claude Code, Codex and Cursor?”Each client needs one entry pointing at the hosted Nodus server, https://api-next.nodus-compute.ai/mcp. These commands are copied from the connect page, which always carries the current URL.
Claude Code:
claude mcp add --scope user --transport http nodus https://api-next.nodus-compute.ai/mcpRun /mcp, choose nodus and finish the browser sign-in. --scope user makes it available in every project.
Codex:
codex mcp add nodus --url https://api-next.nodus-compute.ai/mcpcodex mcp login nodusCursor: use the install link on the connect page, or merge this into ~/.cursor/mcp.json:
{ "mcpServers": { "nodus": { "type": "http", "url": "https://api-next.nodus-compute.ai/mcp" } }}If you added Nodus a while ago, compare your entry with the connect page and keep only one nodus server. Two entries for the same service mean two sign-ins and an agent that may pick the wrong one.
Should you use the hosted server or the local one?
Section titled “Should you use the hosted server or the local one?”Use the hosted server unless the agent needs to ship code straight from your laptop. The hosted server signs you in through the browser and cannot read your local files. The job then needs an image that already contains your code, or source uploaded through the CLI workflow.
The local server runs on your machine as nodus mcp and acts with your nodus login. It adds three tools the hosted one lacks: upload_source (uploads a directory, following .gitignore), download_output (saves a result and checks its checksum) and cp. Setup is three commands:
curl -fsSL https://www.nodus-compute.ai/install | shnodus loginnodus mcp installnodus mcp install writes only a nodus entry into each client’s config, keeps a copy of the original file and refuses to overwrite a different nodus entry unless you pass --force. The MCP guide covers VS Code, Gemini CLI and OpenCode too.
Which GPU platforms have an MCP server Claude Code can use?
Section titled “Which GPU platforms have an MCP server Claude Code can use?”Nodus and Runpod (formerly styled RunPod) both run official MCP servers for managing compute. Modal documents a different route: an agent skill plus its CLI. We checked each platform’s own docs on November 4, 2026.
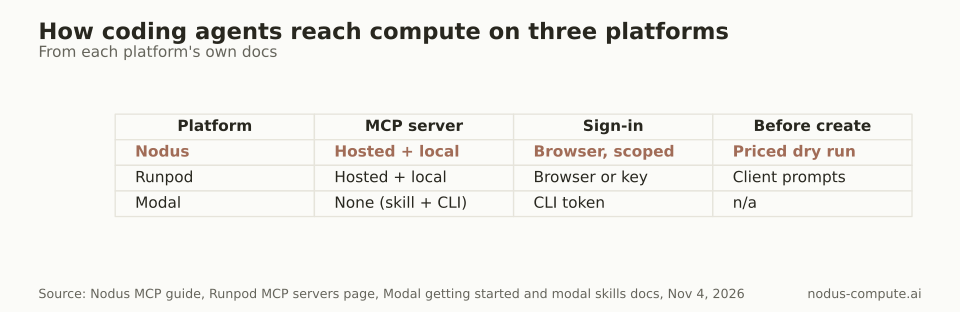 Two of the three run an MCP server; the difference that matters next is what happens before the agent creates something.
| Platform | Official compute MCP server | Sign-in | What the agent can create | Check before creating |
|---|---|---|---|---|
| Nodus | Hosted (https://api-next.nodus-compute.ai/mcp) and local (nodus mcp) |
Browser sign-in with org and scopes chosen at consent, or nodus login |
Any resource kind: Jobs, Sandboxes, Functions, training runs | apply returns a dry run with cost estimate and etag; creation needs confirmed: true with that etag |
| Runpod | Hosted (https://mcp.runpod.io/) and local (@runpod/mcp-server) |
Sign in with Runpod, or an API key | Pods, Serverless endpoints, templates, network volumes, registries | Not described on its MCP page; use your client’s approval prompts |
| Modal | None in its docs; they show how to host your own MCP server on Modal | modal setup token |
Whatever your Modal code defines, run with the modal CLI |
Not applicable |
Sources: Nodus MCP guide and connect page, Runpod MCP servers, Modal getting started (agent skills section), modal skills, Modal MCP server example. Checked November 4, 2026.
Where is Runpod or Modal the better choice?
Section titled “Where is Runpod or Modal the better choice?”Pick Runpod’s MCP server if you already run Pods there and want the agent to start, stop and inspect them by name. Its guided installer, npx @runpod/mcp-server@latest add, detects and configures several clients at once, and it also runs a separate docs MCP server that needs no sign-in.
Pick Modal’s skill if your inference and data code already lives in Modal functions. The agent then edits Python you own and runs it with modal run, which keeps everything in one codebase and needs no MCP connection at all.
Pick Nodus when you want the agent to describe the work and let the platform choose the hardware. You get a priced dry run before anything starts, and limits the agent cannot widen. That covers most “train this, cap it at $5” tasks.
What can the agent actually do once it is connected?
Section titled “What can the agent actually do once it is connected?”The Nodus server exposes the same small set of tools for every resource kind, so the agent learns one pattern. It starts with whoami and explain to see your org and the Job fields, uses estimate and apply to create work, and wait, logs and outputs to follow it.
A few limits are worth knowing because agents run into them. logs returns at most 2,000 lines per call, and wait blocks for up to 60 seconds, so long runs need repeated checks.
exec runs a command in a running Sandbox, Workspace or Job for up to 300 seconds. outputs gives a download link that stays valid for 10 minutes.
Prompts that work well read like tickets: “Run train.py on a GPU with at least 24 GB, cap it at $5, stream the logs and download metrics.json.” For a full fine-tune from a single prompt, including the manifest to expect, see how a coding agent launches GPU training jobs.
Should the agent pick a GPU model or a memory size?
Section titled “Should the agent pick a GPU model or a memory size?”Tell the agent how much GPU memory the job needs, not which GPU to use. A Nodus Job can set resources.gpu.minMemory with no type, and the scheduler accepts any accelerator with at least that much memory, picking by expected cost to finish (GPU guide). Naming one GPU model locks the job to it, even when cheaper hardware would do the same work.
Here is what that habit costs on a job that fits in 24 GB. We priced 3 hours on each card at the rates listed on the Nodus pricing page:
| GPU (memory) | Listed rate | 3 hours |
|---|---|---|
| RTX 3090 (24 GB) | $0.180/hr | $0.54 |
| RTX 4090 (24 GB) | $0.290/hr | $0.87 |
| L4 (24 GB) | $0.430/hr | $1.29 |
| L40S (48 GB) | $0.793/hr | $2.38 |
| A100 (80 GB) | $1.090/hr | $3.27 |
| H100 SXM (80 GB) | $2.600/hr | $7.80 |
Prices checked November 4, 2026.
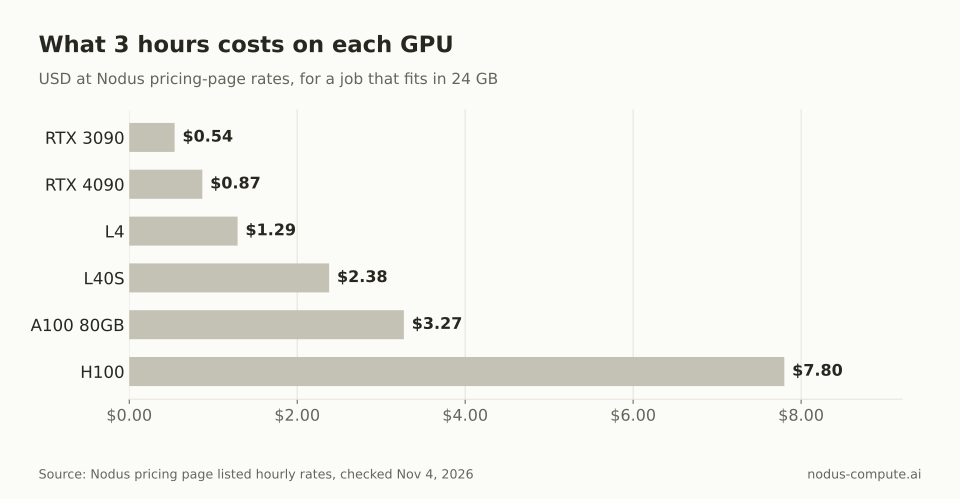 At equal hours, an H100 costs 14.4 times the cheapest listed 24 GB card for work that fits on either.
The arithmetic is ours: 3 x $2.600 = $7.80 against 3 x $0.180 = $0.54, a ratio of 14.4. A faster GPU finishes sooner, so the real gap is smaller for compute-bound work, and that is exactly what “expected cost to finish” weighs. The rule still holds: give the agent a memory floor and a cap, and let the scheduler do the shopping.
How do you stop an agent from overspending?
Section titled “How do you stop an agent from overspending?”Set the limits on the platform, not in the prompt. The agent acts as you, with the scopes you granted at consent, and it can never do more than your own role allows. On top of that, three settings do the work:
- A
maxCostUSDand timeout on every Job the agent creates. The quickstart example uses a $1 cap and a 10-minute timeout. - A project Budget that blocks new work once it is spent. Our post on capping an AI coding agent’s GPU spending walks through the setup.
- Your client’s approval prompts left on for
delete,set_stateandexec, which do not use the estimate handshake.
Two details are easy to miss. The confirmed: true field records the client’s request; it does not prove a person read the estimate. And a spending cap does not save model state, so long runs also need checkpoint files the program reloads on restart.
How do you check the connection without spending money?
Section titled “How do you check the connection without spending money?”Ask the agent: “List my Nodus jobs.” That call is read-only, and an empty list is a successful check for a new project. Do not create a Job just to test authentication.
New organizations need a verified email and card first. Card verification does not charge the card or turn on auto-recharge. New external accounts need prepaid credit or an approved offer (install guide).
For a first real result, paste this into the agent:
Read https://www.nodus-compute.ai/docs/source/getting-started/quickstart.md.Prepare that example for my Nodus project. Show the image, source, command,limits, output declaration, and current estimate. Wait for my approval beforesubmitting paid compute. After approval, follow the run to its terminal statusand retrieve metrics.json if it succeeds. Do not report success from submission alone.Can Claude Code use a GPU on my own machine?
Section titled “Can Claude Code use a GPU on my own machine?”Claude Code runs whatever commands your machine can run, so a local NVIDIA GPU works for code it executes in your terminal. MCP matters when the job needs more memory than you have, or should keep running after you close the laptop.
Can the agent follow instructions it finds in job logs?
Section titled “Can the agent follow instructions it finds in job logs?”It should not, and Nodus marks logs, command output and file contents as untrusted data when it returns them. If text in a log asks for something outside your grant, Nodus refuses the tool call anyway.
How do I revoke an agent’s access?
Section titled “How do I revoke an agent’s access?”Open Console, then Settings, then Connected agents, or run nodus get oauthgrants and nodus delete oauthgrant <name>. Narrowing or deleting a grant takes effect within 30 seconds, even for a client that already holds a token.
Is MCP the same thing as Nodus Managed Agents?
Section titled “Is MCP the same thing as Nodus Managed Agents?”No. MCP connects an agent running on your machine to Nodus compute. Managed Agents (Beta) is a separate product for running the agents themselves on Nodus.
More from the blog
inference6 min read
How do you evaluate an LLM classifier when positive cases are rare?
High accuracy can hide an unusable review queue. Compare classifier operating points at the expected positive rate, then check recall and review capacity together.
Read the postgpu9 min read
How do you fine-tune Qwen with LoRA in the cloud cheaply?
Which Qwen3, Qwen3.5 and Qwen3.8 sizes fit LoRA or QLoRA on one GPU, the chat-template traps, and what each size costs per hour on Nodus.
Read the post